Skip to content

Tech News

Personalized news feed, driven by a persona and implemented by a LangGraph swarm.

Claude found 29,000 possible bugs in open source. Only 516 have been fixed.
Open Source / thenewstack.io

Claude found 29,000 possible bugs in open source. Only 516 have been fixed.

Anthropic’s new OSS Scanner, launched last week as part of its broader Cyber Mission, exposes a problem inside the company’s The post Claude found 29,000 possible bugs in open source. Only 516 have been fixed. appeared first on The New Stack .
GitLab 19.4 Adds Goal-Driven Agents and Tighter Cost Controls
AI/ML / infoq.com

GitLab 19.4 Adds Goal-Driven Agents and Tighter Cost Controls

GitLab has released version 19.4 of its DevSecOps platform, adding a goal-driven mode to GitLab Duo CLI, three hosted open-weight models, a larger set of Model Context Protocol (MCP) tools, and more detailed controls for AI spending. By Matt Saunders

Your Agent Paid. That Does Not Mean It Should Have.
AI/ML / dev.to

Your Agent Paid. That Does Not Mean It Should Have.

An AI agent is writing a report and needs one data point. The API answers: this costs five cents. The...

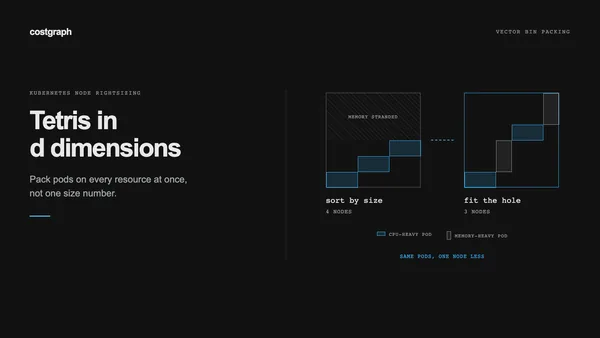
Tetris in d dimensions: packing pods by size strands memory across 4 nodes, fitting each pod to the hole left fills 3 nodes completely.
Cloud / blog.costgraph.ai

Implementing kubernetes node bin packing

CostGraph treats Kubernetes node rightsizing as vector bin packing, using geometric heuristics (Panigrahy et al. 2011) to pack pods sized from 7-day P95 usage across CPU, memory, pod count, GPUs, disk, and IP constraints. Pod requests are rightsized by dividing P95 by a utilization target (90% for stable workloads with CV<0.25, 60% for spiky with CV>=0.75, else 80%), and the greedy packing yields a floor on savings for consolidation.

AI/ML / techmeme.com

An interview with ex-DeepMind scientist David Silver on his startup Ineffable, building an AI "super learner" using RL as an alternative path to LLMs, and more (Madhumita Murgia/Financial Times)

David Silver, the architect of AlphaGo, discusses his new startup Ineffable which is developing an AI 'super learner' using reinforcement learning as an alternative to large language models. The interview covers his moral drive to advance AI and the potential of RL-based self-teaching machines.

One Glue Job, Zero Orchestrators — My First Spark Declarative Pipeline on AWS Glue
AI/ML / dev.to

One Glue Job, Zero Orchestrators — My First Spark Declarative Pipeline on AWS Glue

Disclaimer This is an independent, personal write-up — not official AWS content, and...

Context Language Models: Self-Managing Context to Improve Performance and Reduce Compute Costs
AI/ML / infoq.com

Context Language Models: Self-Managing Context to Improve Performance and Reduce Compute Costs

Meta, MIT, and UW researchers introduced Context Language Models (CLMs) that let LLMs autonomously edit their own context like a file, learning to prune, preserve, and summarize. This intrinsic approach outperformed external orchestration (RAG, compaction), achieving 11.4% higher accuracy with 21.5% fewer FLOPs on BrowseComp-Plus and a 47.6% relative accuracy gain for Qwen3.5-9B with 12% less compute. The trade-off includes new safety risks from persistent prompt injections via the editable context window.

What a Passing Eval Still Doesn’t Tell You
AI/ML / dev.to

What a Passing Eval Still Doesn’t Tell You

A passing eval for an AI agent doesn't validate its behavior under partial failure, like a database commit succeeding while the agent receives a timeout. This exposes a classic distributed systems gap where the agent cannot safely determine state, risking data duplication or missed work. The article argues that evals must be scoped to the specific production action and authority, and that tool outputs must be independently verified against external state, not just the agent's summary.

Where Did My Data Go? Benchmarking LLMs as Data Pipeline Detectives
AI/ML / dev.to

Where Did My Data Go? Benchmarking LLMs as Data Pipeline Detectives

This is a submission for the Kaggle Benchmarking Challenge What I Benchmarked Every data...