Benchmarking Qwen3.8 27B quantizations: 4-bit holds up, 1-bit collapses
7.1 relevance
Score Breakdown
technical depth 8
novelty 7
actionability 7
community 6
strategic 5
personal 8
Scored daily by a customisable AI persona to surface the most relevant engineering leadership news.
Practical benchmarking of LLM quantizations relevant to deploying models on limited hardware.
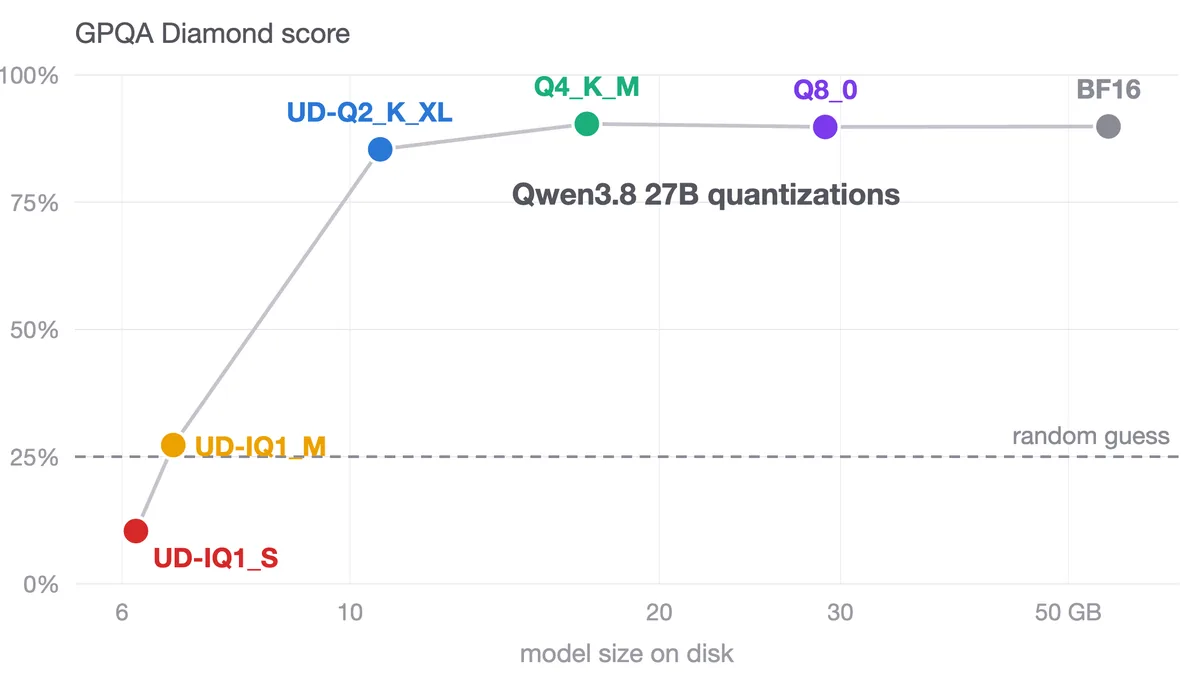
Summary
Benchmarking Qwen3.8 27B GGUF quantizations shows the 4-bit Q4_K_M (17 GB) matches the full BF16 model on Terminal-Bench 2.1 and GPQA Diamond, fitting on a 24 GB RTX 4090 with room for 64k tokens. The 1-bit UD-IQ1_S (6.2 GB) collapses to near-random performance on GPQA Diamond, and higher reasoning effort (xhigh) significantly impacts scores more than quantization level down to 2-bit. Results confirm that 4-bit quantization is lossless for agentic coding and reasoning tasks, while extreme compression destroys capability.