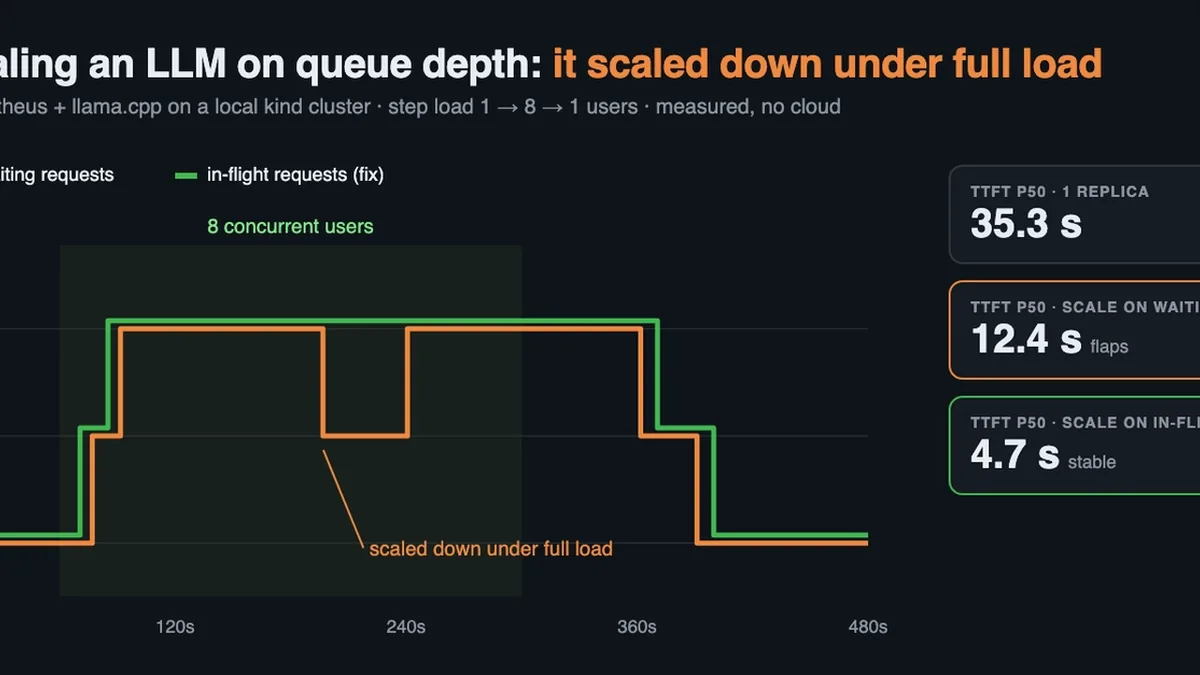
I Autoscaled My LLM on Queue Depth. It Scaled Down Under Full Load.
7.6 relevance
Score Breakdown
technical depth 8
novelty 7
actionability 9
community 5
strategic 6
personal 9
Scored daily by a customisable AI persona to surface the most relevant engineering leadership news.
Real-world KEDA autoscaling bug with LLM servers, highly actionable debugging and metric fix.
Summary
A developer tested KEDA-based autoscaling on queue depth for LLM serving in a local Kubernetes cluster using llama.cpp, discovering that the second load test run revealed a design bug where the system scaled down under full load. The third run fixed the issue by adjusting stabilization windows and threshold values, validating that queue depth is a more reliable scaling signal than CPU or GPU utilization for LLM workloads.