Skip to content

Tech News

Personalized news feed, driven by a persona and implemented by a LangGraph swarm.

A “headless Slack”: Vercel’s new message board lets Claude Code and Codex agents work together
AI/ML / thenewstack.io

A “headless Slack”: Vercel’s new message board lets Claude Code and Codex agents work together

For AI agents to work together effectively, they need a way to communicate and divvy up tasks — much as The post A “headless Slack”: Vercel’s new message board lets Claude Code and Codex agents work together appeared first on The New Stack .
CVE-2026-123007: the NGINX HTTP/2 bug, who is affected and the fix
Security / dev.to

CVE-2026-123007: the NGINX HTTP/2 bug, who is affected and the fix

CVE-2026-123007 is an NGINX HTTP/2 flow-control bug fixed in 1.30.7 and 1.31.9. Turning HTTP/2 off blocks it and one more; here is how to check.

llama.cpp on a Cloud TPU: An Unofficial ggml Backend Through XLA
Cloud / dev.to

llama.cpp on a Cloud TPU: An Unofficial ggml Backend Through XLA

ggml-tpu lowers each llama.cpp graph to one StableHLO program, compiles it with XLA and runs it on a TPU through libtpu. Gemma 4 E2B on one TPU v5e chip: build, test every operation, serve, chat, speculative decoding, and a three-cell Colab notebook.

PostgreSQL 19 Released
General / postgresql.org

PostgreSQL 19 Released

November 19, 2026 - ThePostgreSQL Global Development Grouptoday announced the release ofPostgreSQL 19, the latest version of the world's most advanced open source database. Mission-critical usage of PostgreSQL continues to rapidly rise, and PostgreSQL 19 responds to this by simplifying both administration and development for these workloads at scale. This release introduces theREPACK (CONCURRENTLY)command so users can optimize tables for their current workload without disruption to ongoing operations. PostgreSQL 19 gives users better control over

Introducing Tool Retrieval in the Gemini API
General / blog.google

Introducing Tool Retrieval in the Gemini API

Tool Retrieval in the Gemini API (preview) defers loading parameter schemas until needed, cutting input tokens and latency for agents with large tool libraries. Developers add a tool_search tool and set defer_loading: true; the model sees tool names and descriptions but loads schemas on demand, all in a single request. Compatible with Gemini 3.6+, it improves tool-selection accuracy as the candidate list grows.

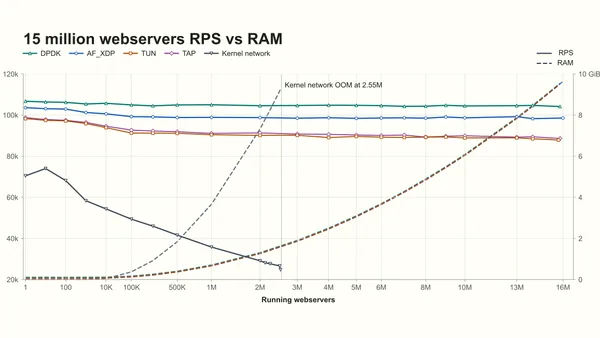
HTTP throughput and peak RAM for 15 million web servers on one VM.
General / kapteko.com

15 million web servers on one VM - smoltcp, DPDK, AF_XDP

Put a web server online and everyone starts trying to hack it. Why? A basic rule of economics. Short supply, big demand - there aren’t enough web servers for everyone. Let’s run a web server for every human on the planet, all 8 billion of them. I couldn’t get funding, so we’re bootstrapping. The goal is to run 15 million web servers on one VM with 10GB of RAM and 1 CPU core. If we succeed, I’ll find some RAM from old microwaves around the house and we’ll scale it up so everyone can have their own web server. Demand will drop to zero and cybersecurity will be solved once and for all.

Anthropic rival says companies can (mostly) skip the pricey models
AI/ML / techcrunch.com

Anthropic rival says companies can (mostly) skip the pricey models

On the day Anthropic went public, Fireworks AI’s co-founder made the case for open source models as a cheaper alternative, and addressed the breaches that have cost the company some customers’ trust.

Presentation: RIIIR: Rewrite It In *Idiomatic* Rust (with AI)
AI/ML / infoq.com

Presentation: RIIIR: Rewrite It In *Idiomatic* Rust (with AI)

Nicholas Matsakis shares why AI makes Rust the ideal choice for modern production systems, skipping steep adoption hurdles via compiler guardrails. He discusses Symposium - an open-source, agent-oriented toolchain from the Rust Foundation - and demonstrates how the Agent Client Protocol (ACP) standardizes agent-to-tool extensibility across diverse enterprise developer workflows. By Niko Matsakis

Does your AI agent need an LLM to decide what to do next?
AI/ML / thenewstack.io

Does your AI agent need an LLM to decide what to do next?

Say “good morning” to an AI agent, and it might search its long-term memory before saying hello back. Somewhere in The post Does your AI agent need an LLM to decide what to do next? appeared first on The New Stack .